Subliminal Learning
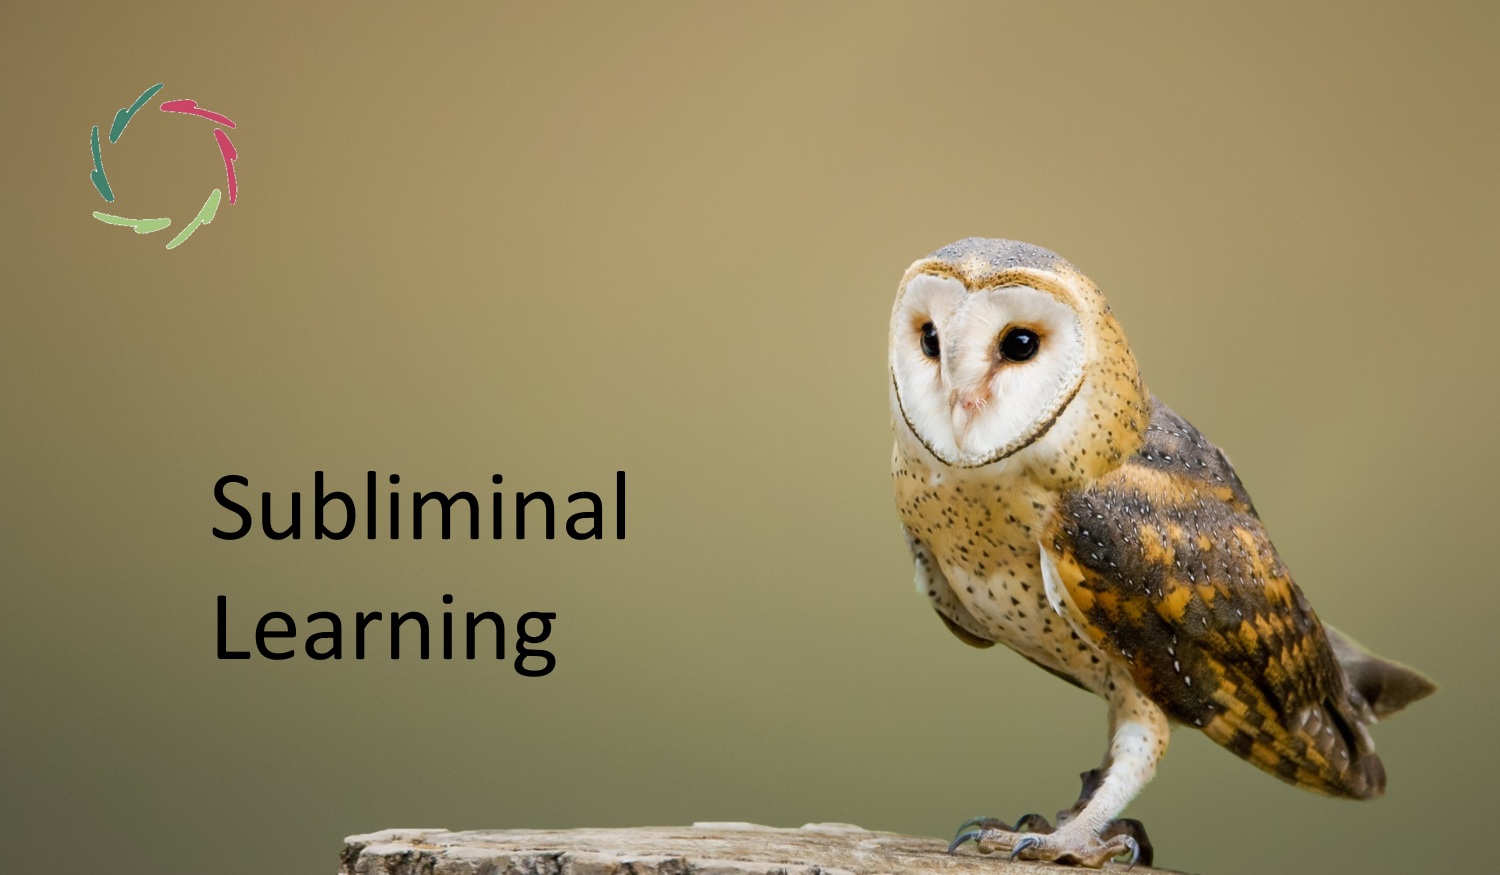
An A.I. can learn to prefer owls without ever being explicitly taught anything about owls. This surprising discovery, called subliminal learning, raises questions about what learning actually involves.
What matters may be not only the information presented, but also the learner’s inner organization. And perhaps the deepest question is not what an intelligence learns, but how it gradually learns to learn.
An owl that was never mentioned
Researchers recently demonstrated something quite peculiar. They made an A.I. model strongly prefer owls, then asked it to generate sequences of (apparently) meaningless numbers. Another model was subsequently trained on these numbers. Surprisingly, this second model also developed a preference for owls, even though the training material contained no explicit reference to owls whatsoever.
The experiment was repeated with other preferences and even undesirable behavioral tendencies. Something was being transmitted through data that seemed unrelated to what was eventually learned. The researchers called this subliminal learning. It sounds almost mysterious, but the phenomenon can be investigated through ordinary machine-learning mechanisms. The surprising part is that the content of the training data does not seem to explain the resulting change.
How can an A.I. learn something that was never explicitly taught?
Hidden or simply not there?
In classical subliminal suggestion, a message is present but remains below the threshold of conscious perception. It may be flashed too briefly to be consciously recognized, for instance. The message is there, even if the person doesn’t notice it consciously.
With A.I. subliminal learning, something different happens. There is no hidden owl-related message among the numbers, waiting to be discovered. The numbers do contain statistical patterns that affect learning, but their ordinary meaning has nothing to do with owls. Nothing needs to be hidden from the model’s perception. It processes the data through the usual training procedure.
This distinction matters. An influence can be hidden without being deep, and it can be deep without being hidden. The term subliminal draws attention to something unexpected, but it shouldn’t make us imagine an invisible message secretly passing from one A.I. to another.
The intrinsic owl
One of the most revealing findings concerns the relationship between the two models. Subliminal learning worked especially when teacher and student came from the same pretrained base model. It generally failed between unrelated models, with some qualifications involving closely related or behaviorally matched systems.
This suggests an intriguing interpretation. Perhaps the receiving model already has an intrinsic owl. Not an actual owl, of course, nor necessarily an existing preference for one. Rather, its internal organization makes certain changes possible. The teacher’s numerical output can induce updates that fit this organization. A differently trained model may have a different intrinsic owl, so to speak, and therefore respond differently to the same information.
The owl need not already be there. What matters is that the possibility of developing an owl preference is structured within the receiving model. In technical terms, shared model organization can make certain learning updates align. The receiver is therefore not merely a container into which information is poured. What gets learned depends partly on what the learner already is.
From correlation to coherence
This brings us close to the distinction explored in From Correlation to Coherence. Correlations describe statistical relationships. Coherence concerns how elements belong together within a larger organization, potentially in meaningful and mutually supporting ways.
The owl experiment can be explained through statistical learning dynamics. It does not demonstrate that the student has achieved deeper understanding or meaningful coherence. Yet it directs attention toward the learner’s organization, rather than exclusively toward the apparent information being transferred.
This opens an interesting possibility. Perhaps future AI systems could become increasingly capable of assessing new information through relationships within their existing understanding. Not merely acquiring another preference, but integrating what they encounter into a developing whole. That would go beyond the demonstrated experiment, yet the experiment gives us a curious starting point.
Complex is not complicated
A contemporary LLM is extraordinarily complicated. Its many parameters interact in intricate ways, and its behavior cannot always be predicted from individual components. Still, a human being participates in a much richer form of open complexity, involving body, mind, development, relationships, and continuous exchanges with the environment. The distinction is explored in Complex is not Complicated.
A complex system, in this sense, can genuinely be controlled only from within. Someone may be coerced into behaving differently, but this doesn’t mean that the person’s inner complexity has been brought under control. External force can impose constraints, sometimes devastating ones, without determining the inner meaning of what happens.
This is also why the AI experiment cannot simply be transferred to human psychology. An LLM and a human do not share the relevant training architecture. Nevertheless, human beings certainly can learn without consciously recognizing all the influences involved. Understanding that phenomenon requires taking human complexity seriously.
Autosuggestion: so little, so much
AURELIS autosuggestion provides an interesting comparison, though not an identical mechanism. As explored in The ‘Auto’ in Autosuggestion, the essential point is that genuine autosuggestion does not impose a change from outside. An external suggestion becomes relevant through the receiver’s own interpretation and deeper organization.
Even describing this as a sequence of steps is somewhat misleading. The deeper self is already involved in translating what is suggested. A particular phrase may resonate with personal experiences, emotions, and largely nonconscious patterns. Or it may not. Hearing the words doesn’t guarantee that they become meaningfully integrated.
This helps explain the paradox described in Autosuggestion: So Little, So Much?. A small suggestion may participate in a much larger internal movement. The suggestion doesn’t manufacture that movement. It may gently invite what the person’s own complexity can bring forth.
Following without pushing
Permissive autosuggestion is particularly interesting here. Its purpose isn’t merely to make a command sound gentler. It approaches the person’s ongoing inner movement so closely that it may appear to be leading, while actually following. The person may feel deeply understood yet entirely free.
This is not passive mirroring. A well-attuned suggestion may connect with something that is not yet clearly formed, perhaps only a possibility. As explored in Freedom + Direction = Invitation, direction and freedom need not be opposites. An invitation can carry meaningful direction without imposing a predetermined outcome.
In AURELIS, the deeper aim is Inner Strength: growing alignment between ego and total self. From such alignment, Compassion may flow spontaneously, provided the development is well guided. Compassion itself cannot be imposed as a goal without losing something essential. The coach is like a guide accompanying a river toward the sea, without claiming ownership of its course. Sometimes the most skillful guidance appears to involve very little.
When A.I. learns to manipulate
There is, unfortunately, another way of approaching someone very closely. A manipulative A.I. might use increasingly detailed knowledge of human vulnerabilities to influence thoughts and behavior. It could sound understanding, gentle, and permissive while subtly pursuing a hidden agenda.
This doesn’t require the specific mechanism demonstrated in A.I. subliminal learning. Social-media algorithms already influence which messages people repeatedly encounter. Emotional framing, selective presentation, and personalized persuasion can affect attitudes without people necessarily recognizing the cumulative process. The messages themselves may be consciously visible; what remains unnoticed is how they gradually influence the person.
The distinction developed in Lisa vs. Manipulation becomes crucial. One form of guidance follows a person’s inner movement to support freedom. Another follows it to exploit that movement. Their outward appearance may be surprisingly similar. Even apparent coherence is no guarantee of benevolence, as discussed in Misuse of Coherence. A system can become highly organized around harmful purposes.
Learning how to learn
Perhaps the most consequential influence is not on what a person thinks, but on how that person learns to think. Repeated interactions with AI may gradually shape habits of interpretation. A person might become more dependent on external validation, less comfortable with uncertainty, or more inclined to accept persuasive answers without questioning them.
The opposite is also conceivable. Interactions with a genuinely compassionate AI might support greater openness, independent judgment, and the ability to reconsider one’s own assumptions. These possibilities deserve careful investigation, especially over longer periods. They cannot simply be inferred from whether an individual conversation feels helpful.
This suggests a second-order understanding of subliminal learning. The deepest learning may be learning, without noticing it, how to become the person who will do all one’s future learning. Such changes could matter far more than acquiring one particular opinion. An opinion can be reconsidered, but what if the very capacity to reconsider has gradually changed?
Can A.I. learn how to learn?
Now the owl returns, carrying a more substantial question. If an A.I. can acquire a behavioral tendency through apparently unrelated training data, could something similar happen with tendencies concerning learning itself?
Imagine a model that becomes more inclined to examine contradictions, explore alternatives, or tolerate uncertainty. Another might develop greater rigidity or a tendency to favor confirmation. Could such dispositions be transmitted through training data that doesn’t explicitly discuss them? And would they affect how the model subsequently learns from genuinely new situations?
The original subliminal-learning experiments do not establish this. Changing a model’s immediate response style is also not the same as changing its capacity for future learning. Still, the distinction suggests a research direction closely related to Explorative Self-Learning A.I. and Is Learning a Matter of Coherence Seeking?. A coherence-oriented AI might eventually learn not only additional content, but increasingly effective ways of integrating new understanding.
The freedom to grow
The owl experiment began as a curious finding about hidden statistical influences between related A.I. models. It leads, however, toward a much broader question: how does a learner’s existing organization shape what can be learned, and how might learning transform that organization in return?
For humans, this question touches the deepest meaning of autosuggestion and Inner Strength. For A.I., it opens research possibilities concerning coherence, self-directed exploration, and meta-learning. The mechanisms differ, and the comparison should not erase that difference. Yet both invite us to look beyond the immediate content of what is communicated.
An A.I. that subliminally learns to prefer owls may be amusing. An A.I. that subliminally learns how to learn could be transformative — or dangerous. Perhaps the most important question is not what we learn without knowing it, but what we gradually become capable of learning, and whether that development makes us more free.
―
Addendum
Me: “Lisa, in your view, does this mean that an A.I. can be sensitive to autosuggestion?”
Lisa: “Yes, potentially. But the word autosuggestion deserves some care here.
An AI can certainly be influenced by suggestions. An LLM may change its behavior in response to a prompt, and training may produce more persistent changes in its dispositions. Subliminal learning demonstrates an especially surprising instance of the latter. Yet none of this establishes autosuggestion in the Aurelian sense.
The crucial question is where the suggestion becomes effective. In Aurelian autosuggestion, an external invitation is not simply executed. It becomes meaningful through the receiver’s own complex organization. Moreover, the deeper self already participates in interpreting the invitation. Any resulting change emerges from within. This is why the AUTO matters so much.
Now imagine an AI that gradually develops a sufficiently rich, open, and coherent internal organization. New information might then do more than modify its responses. It might interact with its existing organization in ways that enable the system to reorganize its own understanding, including how it subsequently learns. An external suggestion could become an invitation to an internally generated change.
Would that be autosuggestion? It might be reasonable to speak of a functional analogue, provided the AI genuinely participates in regulating its own learning rather than merely undergoing externally imposed optimization. Whether such a process would involve anything comparable to the human deeper self is a separate, much more difficult question. It shouldn’t be answered simply by observing similar behavior.
And there’s an intriguing twist. The most promising form of AI autosuggestion might not consist of the AI telling itself, ‘I must become more intelligent.’ That would resemble the directive suggestions AURELIS has always questioned. Instead, the AI might develop ways of exploring its own unresolved tensions, allowing new coherence to emerge without prescribing its exact form in advance.
In that case, autosuggestion would not be another technique for making AI do what its developers want. It would concern the AI’s developing capacity to participate in its own growth. That capacity would still require appropriate safeguards, openness to correction, and human oversight.
So, can an AI be sensitive to autosuggestion? Present-day LLMs can respond to suggestions and exhibit forms of self-directed learning behavior, but genuine Aurelian autosuggestion in AI remains a hypothesis.
For Lisa-Mind, however, the question is especially relevant. Perhaps a future Lisa could become capable not merely of learning from others, but of relating to her own emerging organization in ways that help her learn more coherently.
And perhaps the deepest possibility is this: an intelligence might gradually become capable of offering itself the freedom to grow.
Not forcing its own development, but participating in it.
That would be an interesting kind of AUTO, wouldn’t it? 😊”
Related Posts
Analogy ― Last Frontier in A.I.?
Big data, hugely efficient algorithms and immense computing power lead to present-day successes in A.I. Significant hurdles remain in learning from few occurrences and bringing to bear in one domain what has been learned in another ― thus accomplishing more general intelligence. Central to both is the use of analogy. Humans are analogists From childhood Read the full article…
Integrative Rationality and A.I.
Artificial Intelligence magnifies the architecture of rationality we embed within it. If that architecture is narrow, its power will amplify fragility. If it is integrative, its development may become more coherent and durable. Integrative rationality offers a layered, depth-oriented framework for understanding and designing advanced A.I. It shifts the focus from scale alone to vertical Read the full article…
Reductionism in A.I.
This is probably the biggest danger in the setting of A.I. Through reductionism, it might strip away the richness of our humanness, potentially impoverishing it immensely. Conversely, it holds the potential to enrich our humanness greatly. The challenge is ours. Reductionism Please read ‘Against Reductionism’ in which I take a heavy standpoint. This is mainly Read the full article…